AI & SEO
How to Optimize for AI Search (GEO) + Templates
Published · Last updated
On this page
This guide shows you how to set up a site so AI search products can find, understand and cite it, with concrete steps for each platform and a check after every step. It is written for site owners, marketers and developers who want to do the work themselves. Nobody can guarantee a citation in ChatGPT, Perplexity, Claude or Google, and Google says optimizing for generative AI search is still SEO. A free starter kit of copy-paste files is at the end.
Key takeaways
- Let the right bots in. Search bots decide whether you can be cited, training bots do not, and your CDN or firewall can override robots.txt.
- Put the answer in server-rendered HTML. Several major AI crawlers did not run JavaScript when last measured, so test with plain curl.
- Write answer-first sections: one topic per URL, a direct answer under each heading, explicit facts.
- Structured data must match the visible text. No special schema is required for Google’s AI features.
- llms.txt is optional and Google Search ignores it. It is cheap, so do it after the basics.
- Measure with first-party tools (Search Console, Bing Webmaster Tools, GA4) and repeat your prompt tests over time.
Not sure which platform fits your business? Read WordPress vs Shopify first.
What is GEO?
Generative engine optimization (GEO) means making your pages easy for AI search products to find, understand and cite. Answer engine optimization (AEO) is an overlapping label for the same work, and there is no consensus definition of either, as Wikipedia’s entry notes. Google folds it into SEO, while the Bing Webmaster Guidelines use the term GEO and state that it does not guarantee grounding or citations.
How generative engines find, choose and cite sources
Every engine follows roughly the same path, though the details differ by vendor.
- Crawl: Googlebot (also feeds AI Overviews and AI Mode); Bingbot (Bing, Copilot, grounding API); OAI-SearchBot; Claude-SearchBot; PerplexityBot
- Index: Google: indexed and snippet-eligible; Bing: Copilot shares crawl, index and rank; ChatGPT: third-party search providers plus OAI-SearchBot; Perplexity: real-time web search
- Expand the question: Google: query fan-out; ChatGPT: query rewriting
- Retrieve and select passages: Google: grounding from the Search index; Copilot: parses pages into smaller pieces; Limits: nosnippet, max-snippet, data-nosnippet, Bing NOARCHIVE and NOCACHE
- Generate and cite: Google: links to supporting pages; Perplexity: numbered citations; ChatGPT: citations; Bing: counted citations
- Measure: Search Console Generative AI report (impressions only); Search Console Performance (AI clicks under Web); Bing AI Performance; GA4 utm_source=chatgpt.com; server logs
Training bots are separate: GPTBot, ClaudeBot, Google-Extended (token only). User-triggered fetchers: ChatGPT-User, Claude-User, Perplexity-User.
1. Crawl. Bots have to reach the page. Google’s AI Overviews and AI Mode use the normal Search crawl, Bing’s crawler feeds Copilot, and ChatGPT search relies on OAI-SearchBot, Claude search on Claude-SearchBot, Perplexity on PerplexityBot.
2. Index. Google says a page must be indexed and eligible for a snippet, with no additional requirements. Bing says Copilot shares the same crawl, index and rank foundation. OpenAI says ChatGPT sends rewritten queries to third-party search providers as well as using its own crawler.
3. Expand the question. Google’s guide describes query fan-out, where related sub-queries are issued. OpenAI says ChatGPT rewrites a prompt into one or more targeted queries.
4. Retrieve and select passages. Google retrieves with its core ranking systems. Microsoft says Copilot parses pages into smaller pieces, so key details hidden in tabs, images or PDFs can be skipped.
5. Generate and cite. Perplexity attaches numbered citations to its answers. OpenAI says placement in ChatGPT search is not guaranteed.
Then you measure, which is covered at the end. If you are working on ChatGPT specifically, see our guide to ranking on ChatGPT, and for the wider topic see our answer engine optimization guide.
Training bots, search bots and user-triggered fetchers
Each vendor splits its crawling by purpose. The practical rule: blocking a training token does not remove you from that vendor’s AI search, and blocking a search bot does.
| Vendor | Search and answers | Model training | User-triggered fetch |
|---|---|---|---|
| OpenAI | OAI-SearchBot | GPTBot | ChatGPT-User |
| Anthropic | Claude-SearchBot | ClaudeBot | Claude-User |
| Perplexity | PerplexityBot | Not used for training | Perplexity-User |
| Googlebot (Search, AI Overviews, AI Mode) | Google-Extended token (Gemini training and grounding) | Google user-triggered fetchers | |
| Apple | Applebot | Applebot-Extended token | None documented |
| Microsoft | Bingbot (Bing and Copilot) | No separate token; NOARCHIVE and NOCACHE meta tags | None documented |
Sources: OpenAI, Anthropic, Perplexity, Google, Apple, Bing. Checked October 7, 2026.
SEO vs AEO vs GEO
| SEO | AEO | GEO | |
|---|---|---|---|
| What people mean by it | Earning visibility in classic search results | Being the answer in featured snippets, voice and AI answers | Being cited inside generated answers |
| Where the answer shows up | Ranked links | Answer boxes and assistants | AI Overviews, AI Mode, ChatGPT, Copilot, Perplexity, Claude |
| What you control | Crawlability, content, links, page experience | Answer-first content and clear structure | The same inputs, plus bot access and entity clarity |
| What you measure | Impressions, clicks, rankings | Snippet and answer presence | Citations, impressions in AI reports, referral sessions |
| Caveat | Rankings move | Labels overlap with SEO | No consensus definition, no guaranteed citations |
Google says optimizing for generative AI search is still SEO. Treat the three labels as scope, not as different disciplines.
Six myths to drop before you start
The foundations every platform needs
These six steps apply on every stack. The platform sections later show where each one lives in WordPress, Shopify, React, Next.js and Astro.
1. Let the right bots in: robots.txt and your CDN
StepsOpen the door for search bots
Decide your policy
Template A makes you visible in AI search while opting out of model training. Template B welcomes everything, training crawlers included, and is the policy maxenius.com uses for maximum visibility.
Write the file, repeating shared rules
A crawler obeys only its most specific matching group, and Google’s spec says named groups and the
*group are not combined. So repeat every Disallow line you need inside each named group.public/robots.txtTemplate A: visible in AI search, opted out of training User-agent: * Disallow: /api/ Disallow: /cart/ Allow: / User-agent: OAI-SearchBot User-agent: ChatGPT-User User-agent: Claude-SearchBot User-agent: Claude-User User-agent: PerplexityBot User-agent: Perplexity-User Disallow: /api/ Disallow: /cart/ Allow: / User-agent: GPTBot User-agent: ClaudeBot User-agent: Applebot-Extended User-agent: CCBot Disallow: / Sitemap: https://www.example.com/sitemap.xmlpublic/robots.txtTemplate B: maximum visibility, training crawlers included User-agent: * Disallow: /api/ Allow: / User-agent: OAI-SearchBot User-agent: ChatGPT-User User-agent: GPTBot User-agent: Claude-SearchBot User-agent: Claude-User User-agent: ClaudeBot User-agent: PerplexityBot User-agent: Perplexity-User User-agent: Google-Extended User-agent: Applebot-Extended Disallow: /api/ Allow: / Sitemap: https://www.example.com/sitemap.xmlKeep the mechanics clean
Put Disallow lines before
Allow: /, because simple parsers such as Python’s robotparser stop at the first match. Serve one file per host from/robots.txt. Under RFC 9309, a 5xx response means crawlers assume everything is disallowed, and a 404 means they may crawl everything. robots.txt is not access control. OpenAI and Perplexity both say changes take about 24 hours to apply.Check the layer above robots.txt
OpenAI says your host or CDN must allow its published IP ranges, and Perplexity documents WAF rules that combine user agent and IP lists. Two traps: since September 15, 2026, Cloudflare blocks mixed-purpose crawlers, including Googlebot, Applebot and BingBot, when a customer turns on the training block, and its managed robots.txt prepends Disallow rules that include Google-Extended. On Vercel, setting the AI Bots ruleset to Deny also blocks search bots.
Check it workedCheck it worked
Run
curl -s https://yourdomain.com/robots.txtand confirm the live file matches your repo, since a CDN may rewrite it. Then look in server or CDN logs for 200 responses to OAI-SearchBot, Claude-SearchBot, PerplexityBot and Bingbot. Spoofing a user agent with curl only tests user-agent rules, not IP-based ones.
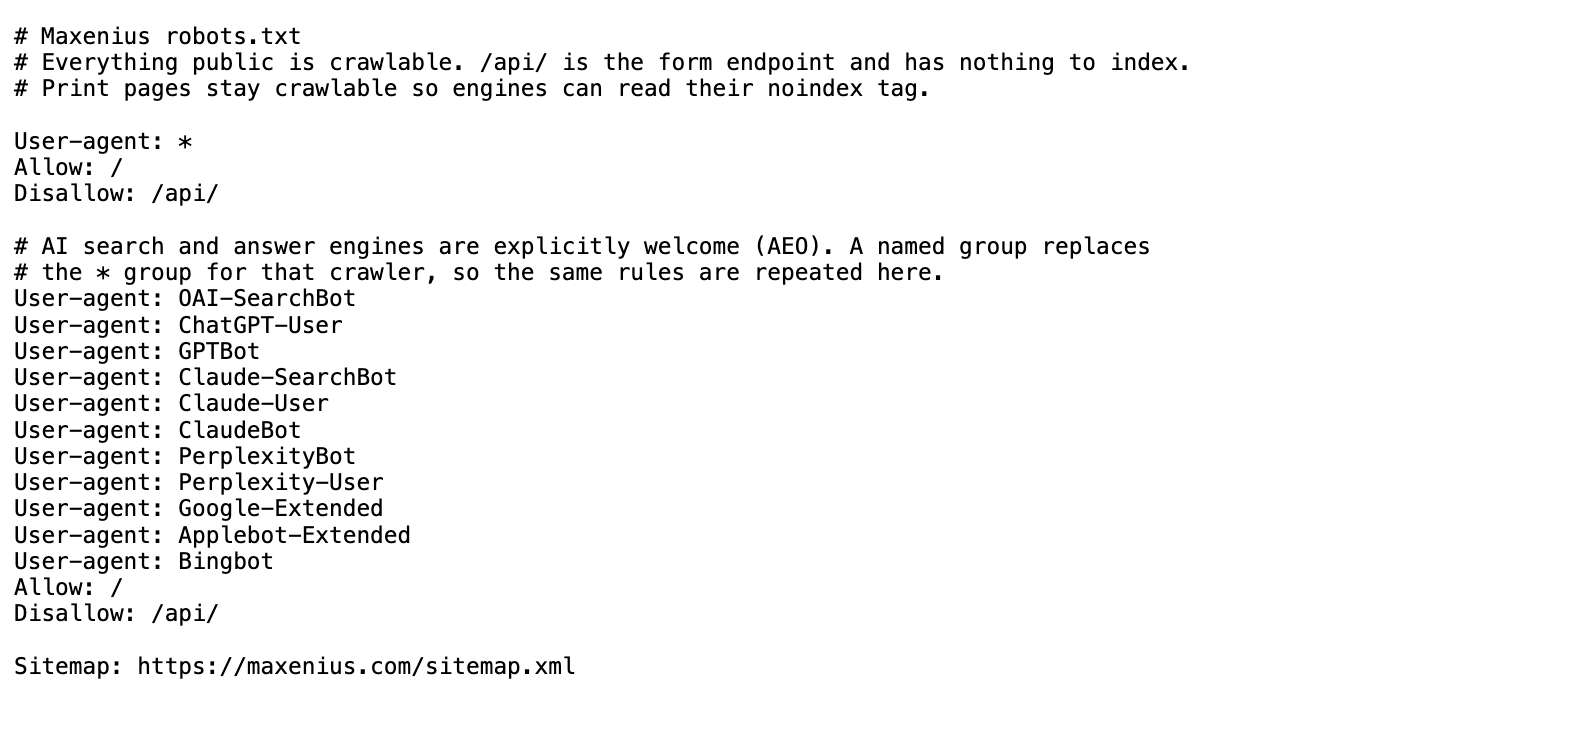
robots.txt templates A and B
Template A: search bots allowed, training bots blocked. Template B, the maximum visibility policy, is in the same folder of the kit.
Any
2. Put the answer in server-rendered HTML
StepsMake the page readable without JavaScript
Read the dated findings first
In December 2024, Vercel and MERJ found that none of the major AI crawlers they studied rendered JavaScript, apart from Gemini through Googlebot and Applebot. Vercel’s 2026 guidance, Make your site readable by AI agents, still advises server-rendering the content you want read. Those are dated findings, not a promise about every crawler. OpenAI does not say whether OAI-SearchBot renders, so test instead of assuming.
Render the essentials on the server
Title, main text, canonical, JSON-LD and navigation links should be in the initial HTML. Google says not all bots run JavaScript, even though Googlebot generally does.
Do not hide answers
Keep key answers out of closed tabs, images and PDFs. Microsoft and Bing both warn against hiding critical content behind client-side rendering.
Check it workedCheck it worked
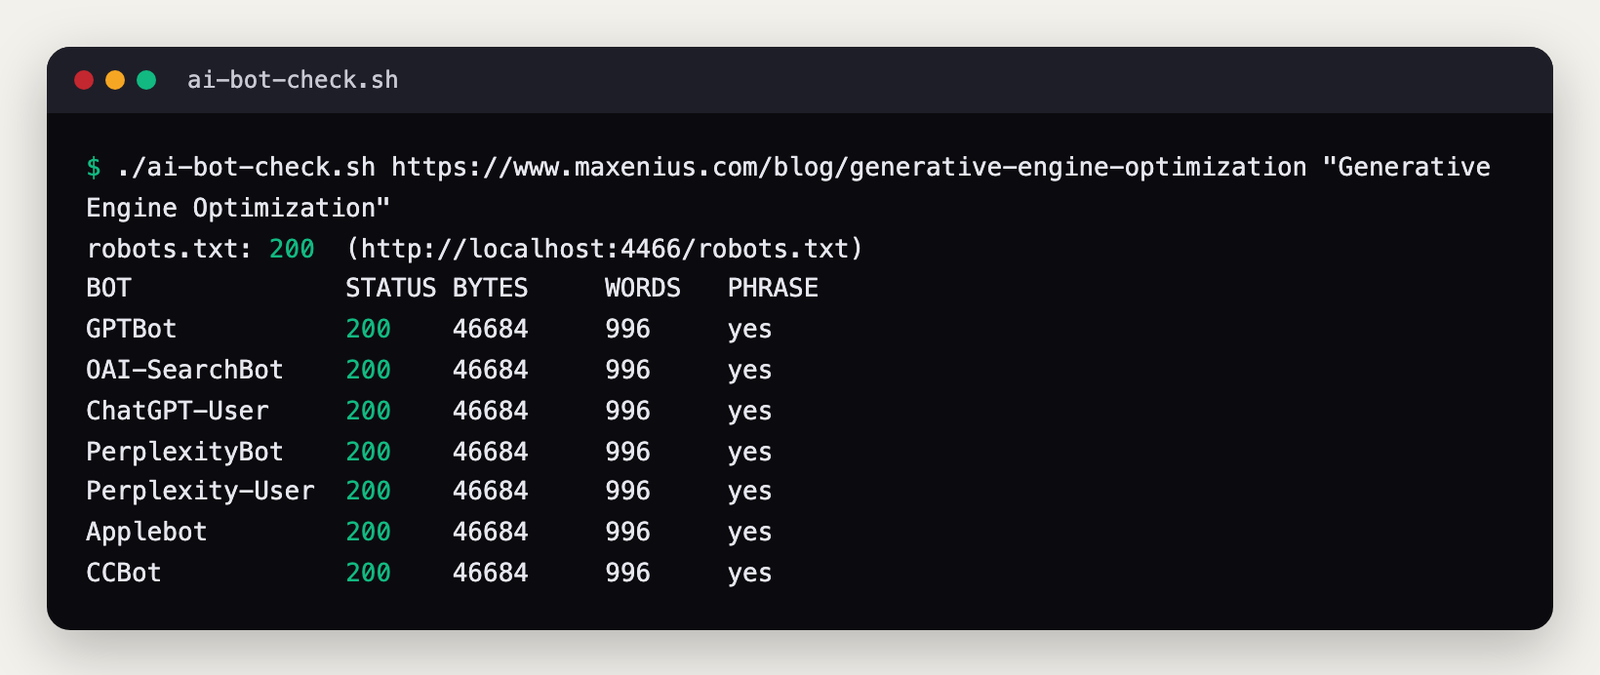
Fetch the page the way a non-rendering crawler does, for example with the kit’s script:
./ai-bot-check.sh https://www.example.com/page "a sentence from the body". Every bot row should show status 200, a word count close to what you see in the browser, and PHRASE = yes. The kit has two scripts:ai-bot-check.shtests seven bot user agents, andcheck-ai-crawl.sh(shown in the frameworks section) checks one fetch for title, canonical and JSON-LD.
3. Write answer-first sections
StepsMake each section liftable
Lead with the answer
Put the direct answer in the first sentences under each heading, and make headings specific. Bing’s guidelines advise surfacing key information early and defining facts explicitly on the URL.
One topic per URL, no scaled pages
Do not create a page for every fan-out variation of a query. Google calls that scaled content abuse. Add first-hand, non-commodity detail instead of restating what others say.
No hidden text for models
Bing treats prompt injection and hidden instructions for LLMs as abuse that can suppress or delist a site. Google says there is no ideal length and no need to chunk, so write for people.
Check it workedCheck it worked
Read each H2 section alone. If it answers its own heading without the paragraph above it, it passes.
4. Structured data that matches the page
StepsAdd markup that tells the truth
Check the requirement
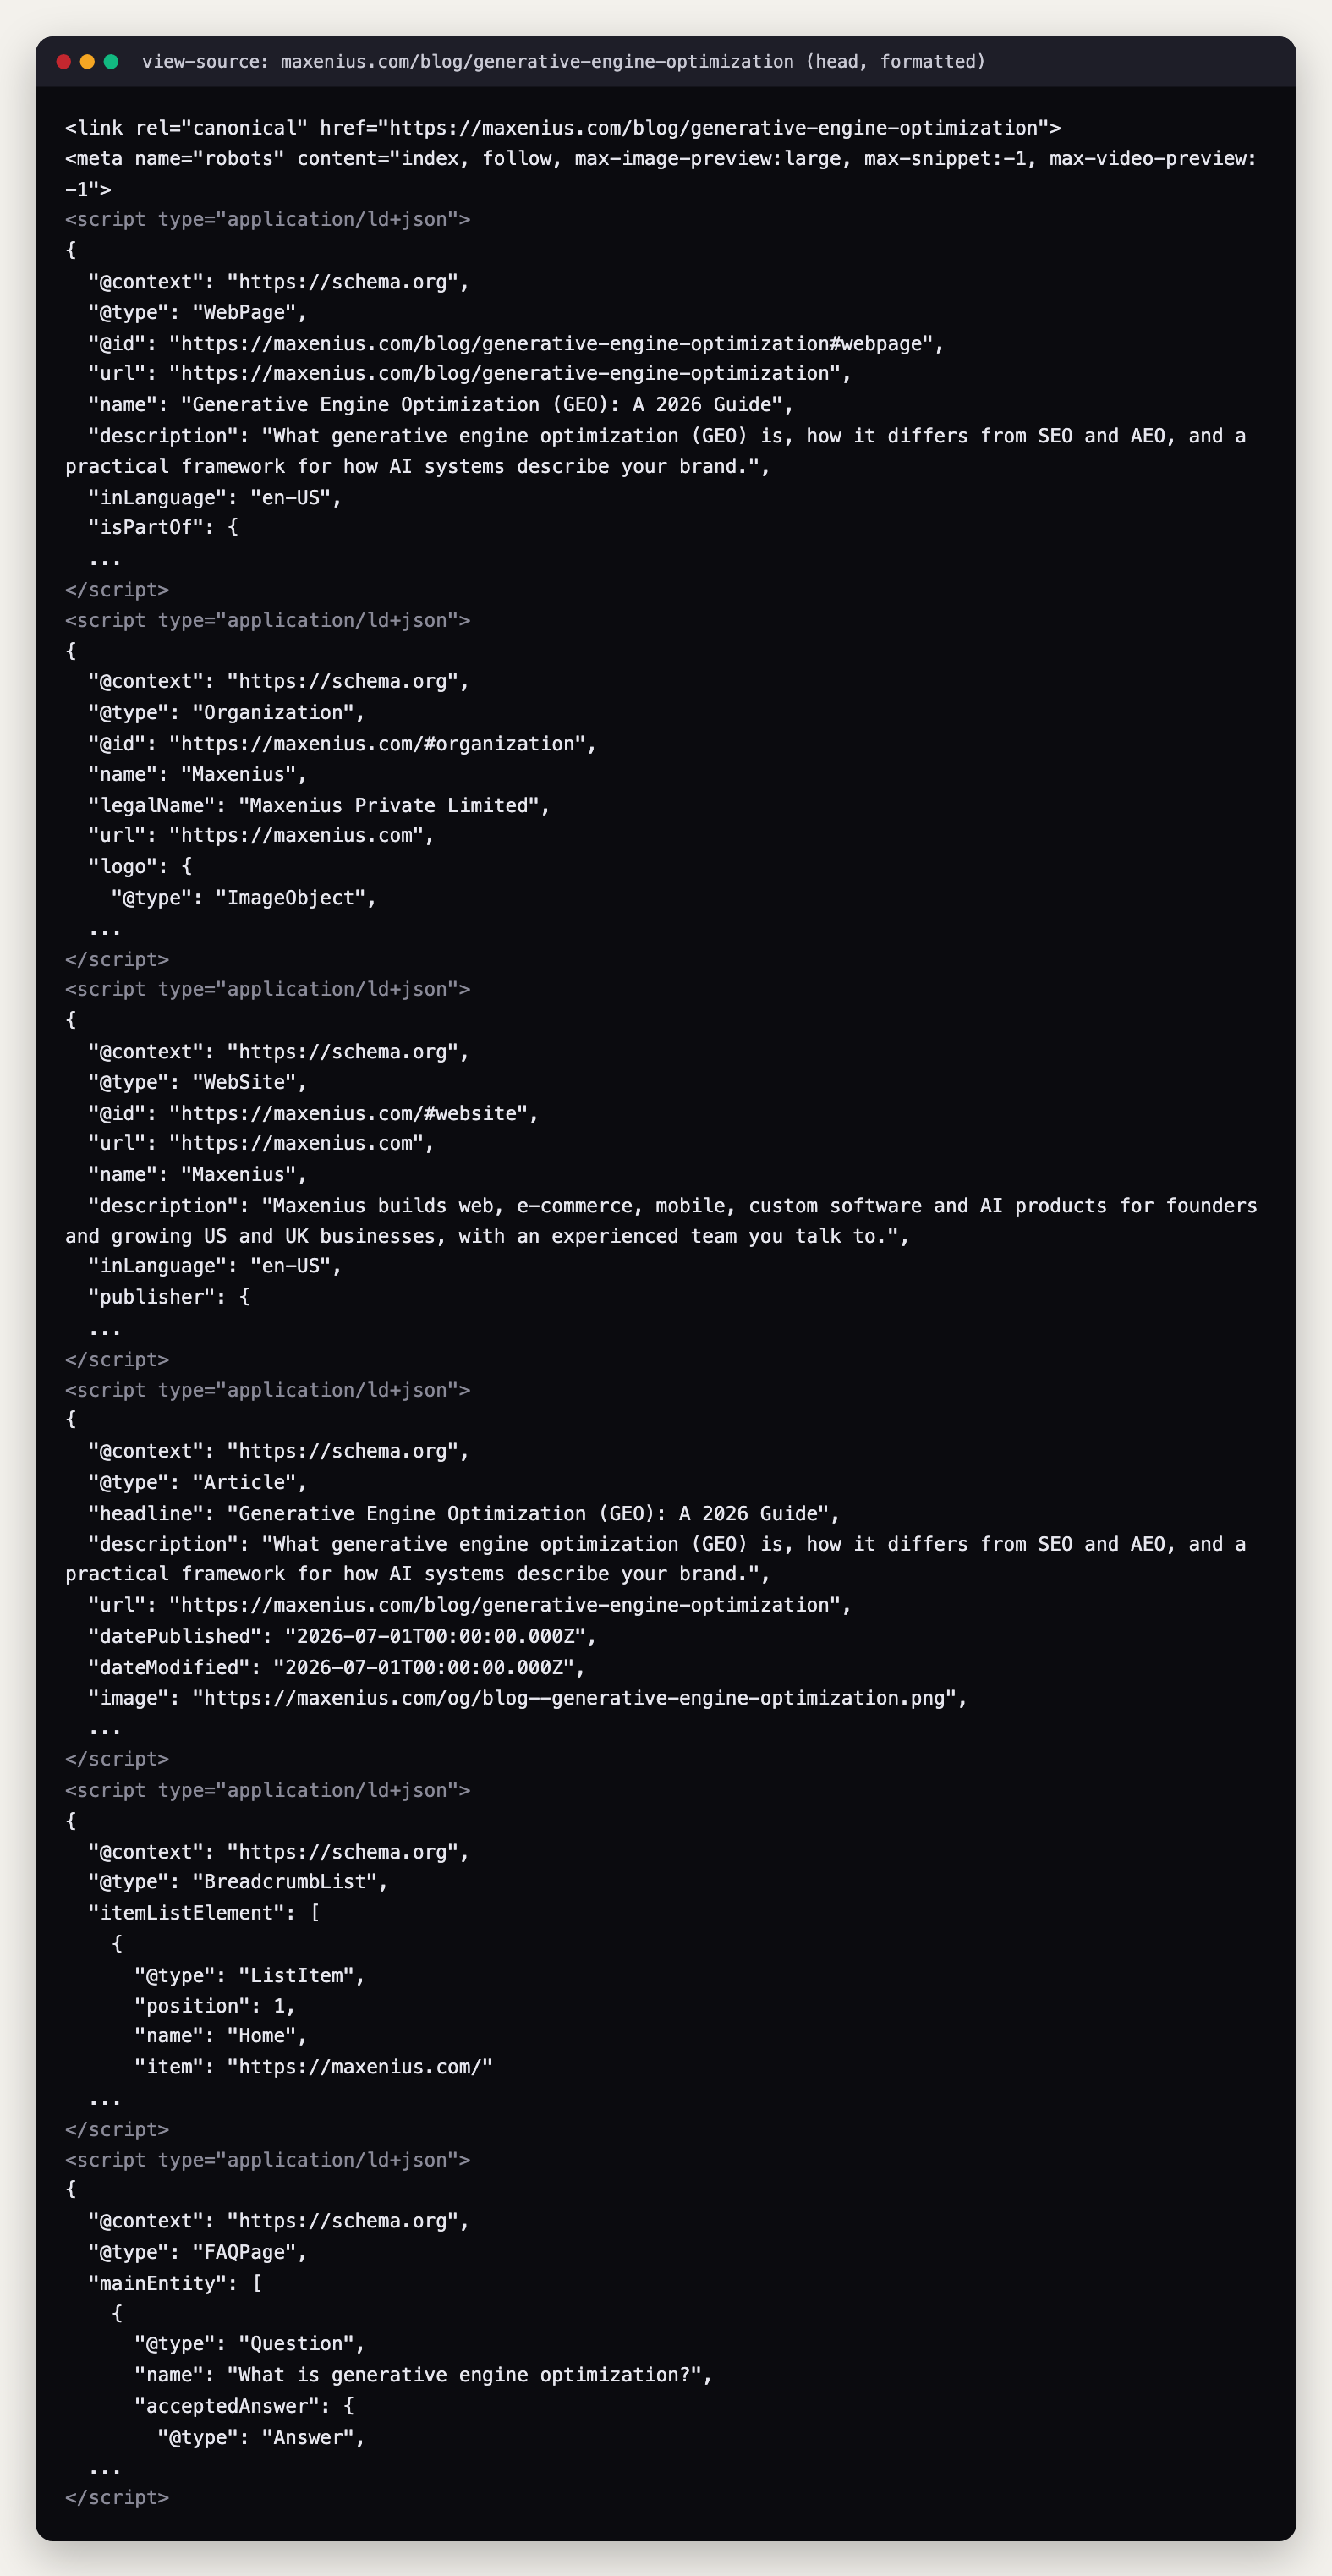
Google says no special schema is needed for AI features, and markup must match visible text. Still use Article or BlogPosting, Organization, Product and BreadcrumbList where they apply.
Use JSON-LD, escape it, and give dates
JSON-LD can sit in the head or body, and Google reads injected JSON-LD, but crawlers that skip JavaScript cannot. When you serialize JSON into a script tag, replace every
<with\u003c(a backslash followed by u003c) so a string containing a closing script tag cannot end the block early. The React, Next.js and Astro samples below do this. Show a visible date and setdatePublishedanddateModifiedto match, per Google’s byline guidance.Treat FAQ schema as optional
Google ended the FAQ rich result on May 7, 2026. Keep FAQ markup only if it mirrors visible questions, and expect no extra SERP space.
Check it workedCheck it worked
View source and confirm the JSON-LD is in the raw HTML. Run the Rich Results Test or Schema Markup Validator, then compare every value against what a visitor sees.
5. What is llms.txt, and do you need one?
llms.txt is an optional community proposal: a Markdown file at /llms.txt that lists your key pages for AI tools. Google says Search does not use it, so you can skip it without losing anything.
StepsDecide whether to publish llms.txt
Know what llms.txt is
llms.txt is a Markdown file at your site root, proposed by Jeremy Howard on September 3, 2024, with a v2 format published in August 2026. It has an H1 (the only required part), an optional blockquote summary, and H2 sections listing links as
- [name](url): notes.What it does today
Google says Search neither harms nor helps from it. None of the crawler documents we reviewed from OpenAI, Anthropic, Perplexity, Bing, Apple or Meta says their crawler reads it. Chrome’s Lighthouse has an Agentic Browsing audit that is marked Not Applicable when the file is missing. Vercel’s 2026 guidance reports that adding llms.txt did not change retrieval when the answer was already in server HTML, and that 86 percent of attributed fetches arrived through page links.
Decide whether to publish it
Optional and cheap, so do it after the basics. Keep it small.
llms-full.txtis a convention some documentation platforms generate, not part of the spec, and real ones run to tens of megabytes. Shopify’s default/llms.txtserves agent instructions, covered in the Shopify section.public/llms.txtPlaceholder facts, v2 format # Example Co > Example Co makes refillable cleaning products and sells them online to customers in the US and Canada. Key facts: - Free shipping on US orders over $50; returns accepted within 30 days. - Support: support@example.com, Monday to Friday. ## Products - [All products](https://www.example.com/collections/all): Full catalog with prices and stock status - [Refill subscriptions](https://www.example.com/pages/subscriptions): How refills are billed, paused and cancelled ## Policies - [Shipping policy](https://www.example.com/policies/shipping-policy): Carriers, delivery times and costs - [Refund policy](https://www.example.com/policies/refund-policy): Return window and how refunds are paidCheck it workedCheck it worked
Run
curl -sI https://yourdomain.com/llms.txtand expect 200 with a text content type. Then paste only the file into an assistant and ask it questions about your business.
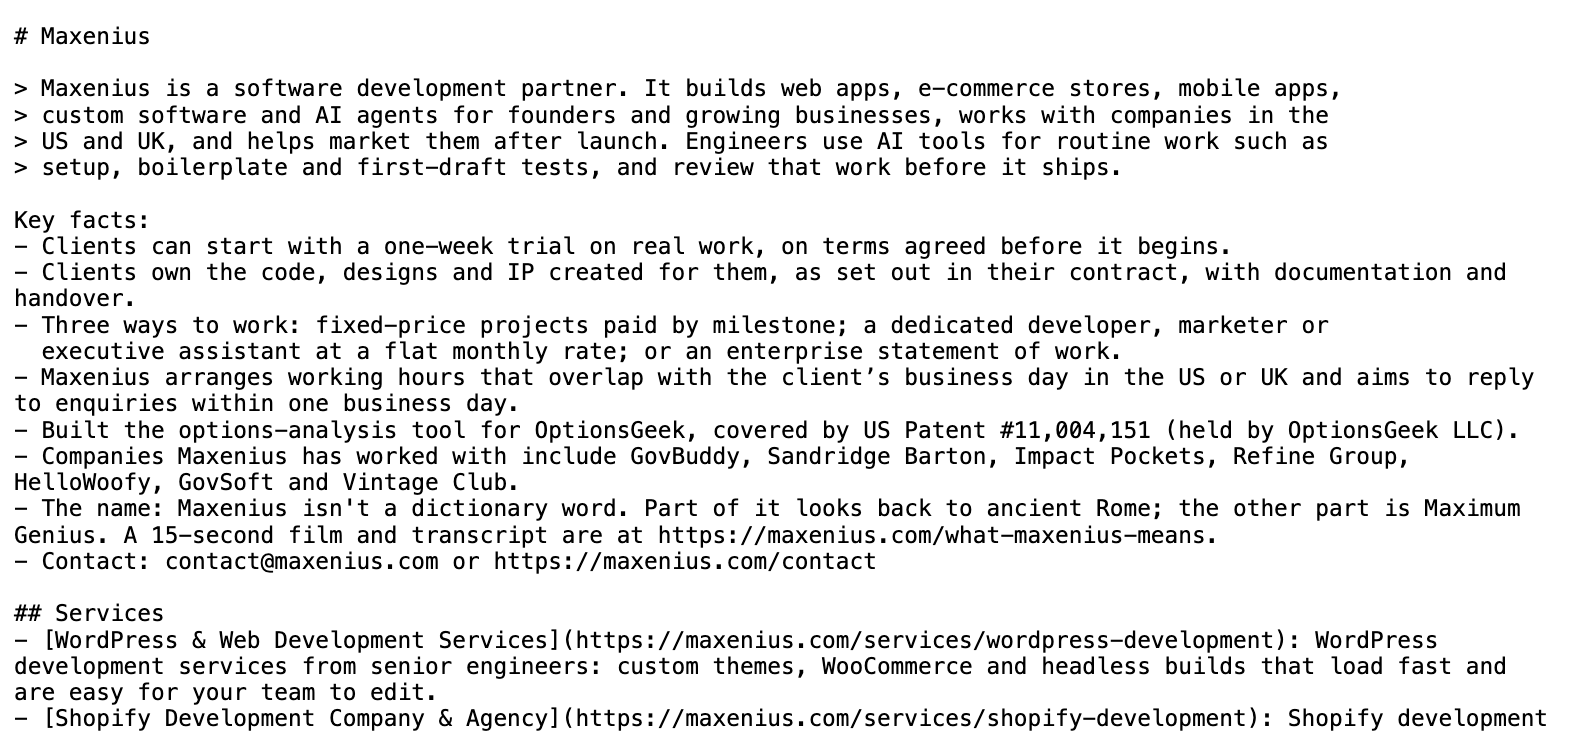
llms.txt starter
The example above as a download, with placeholder facts to replace.
Any
6. Keep your entity and your URLs consistent
StepsSay who you are once, at one address
Publish Organization markup
Add Organization JSON-LD on the home page with name, url, logo, description and
sameAslinks to your real profiles, following Google’s Organization doc. Use the same name everywhere, as Bing’s guidelines ask, and keep Business Profile, Bing Places and Merchant Center data in step.Pick one host
Your canonical tag, sitemap
locvalues and redirect target must agree. Google treats redirects and rel=canonical as strong signals and the sitemap as weak, and advises against declaring different URLs by different methods. Bing notes that LLMs cluster near-duplicates and may pick an outdated URL to represent them.Set lastmod from real changes
Change
lastmodonly when the main content, structured data or links change, never to the build time. Google ignorespriorityandchangefreq, and Bing says the same. Pair it with a visible date anddateModified.Ping IndexNow for Bing
IndexNow notifies Bing and other participating engines of changes. Google is not a participant. An HTTP 200 means your URL was received, not indexed.
Check it workedCheck it worked
Run
curl -sI https://example.com/page | grep -i -E '^HTTP/|^location'for each host variant, then compare the redirect target with the page’s canonical and its sitemap entry. All three must be the same URL.
Organization JSON-LD
Entity markup template with placeholder values and sameAs links.
Any
How to optimize WordPress for AI search (and add llms.txt): step-by-step
This section works on a standard WordPress site with or without an SEO plugin. Each step ends with a one-line check, and the last step runs four terminal commands that confirm the whole setup.
Find your SEO plugin’s settings
Most of the choices below depend on this table. Find your column first, then follow the steps.
| Yoast SEO | Rank Math | AIOSEO | |
|---|---|---|---|
| llms.txt | Free since 25.3 (June 10, 2025). Yoast SEO > Settings > Site features > AI tools > LLMS.txt. Writes a physical file, refreshed weekly. Yoast has said it is not available on multisite (GitHub issue). | Since 1.0.250 (July 31, 2025). Enable the module at Rank Math SEO > Dashboard, then Rank Math SEO > General Settings > Edit llms.txt. Empty until you configure it. | Built in; see the AIOSEO changelog. Includes llms-full.txt and Markdown versions of posts. All in One SEO > Sitemaps > LLMs.txt tab. Enabled by default, written as a static file. |
| robots.txt editor | Yoast SEO > Tools > File editor > Create robots.txt file. This creates a physical file. | Rank Math SEO > General Settings > Edit robots.txt. Virtual file; per Rank Math’s KB, a physical file in the root blocks editing. | All in One SEO > Tools > Robots.txt Editor > Enable Custom Robots.txt. Includes a Block AI Crawlers option. |
| Sitemap URL | /sitemap_index.xml (core’s /wp-sitemap.xml is replaced) | /sitemap_index.xml | Virtual sitemap, managed under All in One SEO > Sitemaps |
| IndexNow | Premium only | Instant Indexing module | Built in |
WordPress core serves /wp-sitemap.xml on its own. With no SEO plugin, the official IndexNow plugin covers IndexNow.
StepsSet up WordPress for AI search
Make sure the content is in the HTML
Open a key page, choose View Source (not Inspect), and search for a sentence from the body. Or run
curl -s https://example.com/page/ | grep -i "a sentence from the page". Themes and mainstream page builders render on the server, but content in AJAX tabs, sliders and “load more” widgets may not be there.Make sure navigation uses real
<a href>links, because Google can only crawl links built that way. Then open Settings > Reading and confirm “Search engine visibility” is unchecked. When it is on, current WordPress adds a noindex robots meta to every page rather than a robots.txt Disallow.Check: your sentence appears in the curl output, and
curl -s https://example.com/ | grep -i noindexreturns nothing.Take control of robots.txt
With no physical file, WordPress builds a virtual robots.txt and passes it through the
robots_txtfilter. A physical robots.txt in the web root overrides that filter and every plugin editor in the table, and Yoast’s File editor creates exactly such a file. Find out which situation you are in before editing anything.If you want an explicit AI group, use the geo-robots.php mu-plugin below. It repeats the admin rules inside the group, because under RFC 9309 a crawler that finds a group naming it obeys only that group.
Leave AIOSEO’s Block AI Crawlers and Yoast Premium’s Bot blocker off if you want AI search visibility. If the site sits behind Cloudflare, check its managed robots.txt, which adds Disallow rules above your file.
Check:
curl -s https://example.com/robots.txtshows the rules you expect. OpenAI says changes can take about 24 hours to reach ChatGPT search.Decide which bots to allow
Search and citation bots are OAI-SearchBot, Claude-SearchBot and PerplexityBot. Training bots such as GPTBot and ClaudeBot are a separate decision, and blocking them does not remove you from that vendor’s search. The full vendor table is in the foundations section.
Check: each bot you want in search is not named in a Disallow group.
Publish llms.txt from one source only
Pick the plugin feature in the table, or use geo-llms-txt.php if you have no plugin. Never run two. Yoast will not overwrite an existing file, and a static file can mask a dynamic one from another plugin.
The payoff is uncertain, as covered in the llms.txt section. Rank Math’s own documentation says adoption is limited. It costs little, so treat it as a tidy index of your best pages.
Check:
curl -sI https://example.com/llms.txtreturns 200, and the body starts with# Your site name.Add structured data through your plugin
Do not paste a second Organization block. Yoast outputs one linked @graph and exposes filters such as
wpseo_schema_organization(Schema API). Set the name, logo and profiles first at Yoast SEO > Settings > Site representation. Rank Math lets you extend the publisher throughrank_math/json_ld. Without a plugin, use geo-schema.php.Check:
curl -s https://example.com/ | grep -c 'application/ld+json', then paste each block into validator.schema.org and confirm there is one Organization node.Fill in author and entity details
Complete Users > Profile (display name, biographical info, website) because SEO plugins read author data from it. Per Google’s Article guidance,
author.nameholds only the name andauthor.urlpoints to a page that uniquely identifies the author. For the company, Organization markup belongs on the home or About page and recommends name, url, logo, sameAs and contact details.Check: a post’s byline links to an author page, and the page source shows the same name in the Article JSON-LD.
Link internally with descriptive anchors
From each hub page (services, category, guide) link to detail pages with anchor text that describes the target. “Our WooCommerce setup checklist” tells a crawler more than “read more”.
Check: every important page has at least one text link pointing to it from another page.
Run one sitemap generator
Use core, Yoast, Rank Math or AIOSEO, not several. Submit the URL in Google Search Console and Bing Webmaster Tools. Bing asks for accurate lastmod values in ISO 8601 with date and time.
Check: the sitemap URL from the table loads, and lastmod changes only when you actually edit a page.
Turn on IndexNow, one sender
Choose the official IndexNow plugin, Rank Math’s Instant Indexing, AIOSEO, or Yoast Premium. Running two duplicates submissions. IndexNow shares submitted URLs with all participating engines.
Check: publish a test post and look for it in the plugin’s recent submissions list.
Complete WooCommerce product data
For each product, fill Product data > Inventory > SKU and the “GTIN, UPC, EAN, or ISBN” field, and write a real short description. WooCommerce 11.1.2 outputs Product JSON-LD with sku, gtin, offers and ratings, and lets you extend it with
woocommerce_structured_data_product. The filters file below adds a brand. If an SEO plugin also outputs Product, compare the two blocks.WooCommerce trunk has OnlineStore and MerchantReturnPolicy markup planned for a later release (marked 11.3.0), so it is not in 11.1.2.
Check: view source on a product page and confirm exactly one Product node with your GTIN in it.
Check it workedVerify everything from a terminal
Replace the domain and phrase, then run all four:
curl -s https://example.com/robots.txtshows your intended groups and a Sitemap line.curl -sI https://example.com/llms.txtreturns 200 and text/plain.curl -s https://example.com/ | grep -c 'application/ld+json'returns the number of blocks you expect.curl -s https://example.com/some-page/ | grep -i "a sentence from the body"finds your text.
Code you can drop in
Place these files in wp-content/mu-plugins/. WordPress loads top-level PHP files there automatically. Each file is also in the starter kit.
<?php
/**
* Plugin Name: GEO robots.txt rules
* Description: Adds an explicit group for AI search crawlers to the virtual robots.txt.
*/
defined( 'ABSPATH' ) || exit;

add_filter(
'robots_txt',
function ( $output, $is_public ) {
	if ( ! $is_public ) {
		return $output;
	}
	$admin_path = wp_parse_url( admin_url(), PHP_URL_PATH );
	$ajax_path  = wp_parse_url( admin_url( 'admin-ajax.php' ), PHP_URL_PATH );
	// A crawler that finds a group naming it obeys only that group (RFC 9309).
	$bots  = array( 'OAI-SearchBot', 'ChatGPT-User', 'Claude-SearchBot', 'Claude-User', 'PerplexityBot', 'Perplexity-User' );
	$group = "\n# AI search and answer crawlers\n";
	foreach ( $bots as $bot ) {
		$group .= 'User-agent: ' . $bot . "\n";
	}
	$group .= 'Disallow: ' . $admin_path . "\n";
	$group .= 'Allow: ' . $ajax_path . "\n";
	return $output . $group;
},
99,
2
);
Output, appended after the core default:
# AI search and answer crawlers
User-agent: OAI-SearchBot
User-agent: ChatGPT-User
User-agent: Claude-SearchBot
User-agent: Claude-User
User-agent: PerplexityBot
User-agent: Perplexity-User
Disallow: /wp-admin/
Allow: /wp-admin/admin-ajax.php<?php
/**
* Plugin Name: GEO llms.txt
* Description: Serves /llms.txt (llmstxt.org format) without an SEO plugin.
* A physical llms.txt in the web root wins over this code.
*/
defined( 'ABSPATH' ) || exit;
const GEO_LLMS_REWRITE_VERSION = '1';
add_action( 'init', function () {
add_rewrite_rule( '^llms\.txt$', 'index.php?geo_llms_txt=1', 'top' );
// mu-plugins have no activation hook, so flush once per rule version.
if ( get_option( 'geo_llms_rewrite_version' ) !== GEO_LLMS_REWRITE_VERSION ) {
flush_rewrite_rules( false );
update_option( 'geo_llms_rewrite_version', GEO_LLMS_REWRITE_VERSION );
}
} );
add_filter( 'query_vars', function ( $vars ) {
$vars[] = 'geo_llms_txt';
return $vars;
} );
// Priority 0 runs before redirect_canonical (priority 10).
add_action( 'template_redirect', function () {
if ( ! get_query_var( 'geo_llms_txt' ) ) {
return;
}
$body = get_transient( 'geo_llms_txt_body' );
if ( false === $body ) {
$body = geo_llms_build();
set_transient( 'geo_llms_txt_body', $body, 12 * HOUR_IN_SECONDS );
}
status_header( 200 );
header( 'Content-Type: text/plain; charset=utf-8' );
echo $body; // phpcs:ignore WordPress.Security.EscapeOutput.OutputNotEscaped
exit;
}, 0 );
add_action( 'save_post', function () {
delete_transient( 'geo_llms_txt_body' );
} );
function geo_llms_build() {
$clean = function ( $text ) {
$text = wp_strip_all_tags( html_entity_decode( (string) $text, ENT_QUOTES, 'UTF-8' ) );
return trim( preg_replace( '/\s+/', ' ', $text ) );
};
$lines = array( '# ' . $clean( get_bloginfo( 'name' ) ), '' );
$tagline = $clean( get_bloginfo( 'description' ) );
if ( '' !== $tagline ) {
$lines[] = '> ' . $tagline;
$lines[] = '';
}
$sections = array(
'Pages' => array( 'post_type' => 'page', 'orderby' => 'menu_order title', 'order' => 'ASC' ),
'Articles' => array( 'post_type' => 'post', 'orderby' => 'modified', 'order' => 'DESC' ),
);
if ( post_type_exists( 'product' ) ) {
$sections['Products'] = array( 'post_type' => 'product', 'orderby' => 'modified', 'order' => 'DESC' );
}
foreach ( $sections as $heading => $args ) {
$posts = get_posts( array_merge( $args, array(
'post_status' => 'publish', 'posts_per_page' => 50, 'has_password' => false, 'suppress_filters' => false,
) ) );
if ( ! $posts ) {
continue;
}
$lines[] = '## ' . $heading;
$lines[] = '';
foreach ( $posts as $post ) {
$summary = $clean( has_excerpt( $post ) ? get_the_excerpt( $post ) : wp_trim_words( strip_shortcodes( $post->post_content ), 30, '' ) );
$title = str_replace( array( '[', ']' ), array( '(', ')' ), $clean( get_the_title( $post ) ) );
$line = sprintf( '- [%s](%s)', $title, esc_url_raw( get_permalink( $post ) ) );
if ( '' !== $summary ) {
$line .= ': ' . $summary;
}
$lines[] = $line;
}
$lines[] = '';
}
return implode( "\n", $lines );
}This version does not know about per-post noindex flags from SEO plugins, which is another reason to use it only on sites without one.
<?php
defined( 'ABSPATH' ) || exit;

function geo_print_jsonld( array $data ) {
echo '<script type="application/ld+json">'
	. wp_json_encode( $data, JSON_UNESCAPED_SLASHES | JSON_UNESCAPED_UNICODE | JSON_HEX_TAG )
	. "</script>\n";
}

// Organization on the front page (edit the values).
add_action( 'wp_head', function () {
if ( ! is_front_page() ) {
	return;
}
geo_print_jsonld( array(
	'@context'     => 'https://schema.org',
	'@type'        => 'Organization',
	'@id'          => home_url( '/#organization' ),
	'name'         => get_bloginfo( 'name' ),
	'url'          => home_url( '/' ),
	'logo'         => get_site_icon_url( 512 ),
	'description'  => get_bloginfo( 'description' ),
	'sameAs'       => array( 'https://www.linkedin.com/company/your-company' ),
	'contactPoint' => array( '@type' => 'ContactPoint', 'contactType' => 'sales', 'email' => 'hello@example.com' ),
) );
} );

// FAQPage from a "geo_faqs" custom field: [{"q":"...","a":"..."}]. Mark up only visible FAQs.
add_action( 'wp_head', function () {
if ( ! is_singular() ) {
	return;
}
$faqs = json_decode( (string) get_post_meta( get_queried_object_id(), 'geo_faqs', true ), true );
if ( ! is_array( $faqs ) || ! $faqs ) {
	return;
}
$entities = array();
foreach ( $faqs as $faq ) {
	if ( empty( $faq['q'] ) || empty( $faq['a'] ) ) {
		continue;
	}
	$entities[] = array(
		'@type'          => 'Question',
		'name'           => wp_strip_all_tags( $faq['q'] ),
		'acceptedAnswer' => array( '@type' => 'Answer', 'text' => wp_kses_post( $faq['a'] ) ),
	);
}
if ( $entities ) {
	geo_print_jsonld( array( '@context' => 'https://schema.org', '@type' => 'FAQPage', 'url' => get_permalink(), 'mainEntity' => $entities ) );
}
} );<?php
defined( 'ABSPATH' ) || exit;
// Yoast SEO: extend the Organization piece from Settings > Site representation.
add_filter( 'wpseo_schema_organization', function ( $data ) {
$data['description'] = 'One plain sentence on what the company does and for whom.';
$data['email'] = 'hello@example.com';
return $data;
} );
// Rank Math: the publisher entity lives at $data['publisher'].
add_filter( 'rank_math/json_ld', function ( $data, $jsonld ) {
if ( isset( $data['publisher'] ) && is_array( $data['publisher'] ) ) {
$data['publisher']['description'] = 'One plain sentence on what the company does and for whom.';
}
return $data;
}, 99, 2 );
// WooCommerce core Product markup: add a brand.
add_filter( 'woocommerce_structured_data_product', function ( $markup, $product ) {
$markup['brand'] = array( '@type' => 'Brand', 'name' => get_bloginfo( 'name' ) );
return $markup;
}, 10, 2 );geo-robots.php
AI crawler group for the virtual robots.txt.
WordPress
geo-llms-txt.php
llms.txt without an SEO plugin.
WordPressWooCommerce
geo-schema.php
Organization and FAQ JSON-LD without an SEO plugin.
WordPress
geo-schema-plugin-filters.php
Filters for Yoast, Rank Math and WooCommerce.
WordPressWooCommerce
For hands-on help, see our WordPress development team.
How to optimize Shopify for AI search and ChatGPT: step-by-step
Shopify already does most of the technical work. As of October 7, 2026, every store ships with an automatic sitemap.xml that you cannot edit, a default robots.txt, and JSON-LD from the structured_data filter in the Dawn and Horizon themes. Since May 28, 2026, every store also serves default /agents.md, /llms.txt and /llms-full.txt files, per the Shopify changelog.
One limit: nothing here guarantees that ChatGPT, Copilot or Gemini will show your products. Shopify says optimizing product data raises the chances, not that it ensures them.
StepsSet up a Shopify store for AI search
Check what your store already serves
Open these four URLs on your store and note what you see:
/robots.txt,/llms.txt,/agents.mdand/sitemap.xml.Do not expect your robots.txt to match anyone else’s. On October 7, 2026 we saw newer stores serving a default whose comments point agents to
/agents.md, and other stores still serving the older default with extra groups for tools like Nutch, AhrefsBot and Pinterest. Both leave AI crawlers under*.The default
/llms.txtis a set of agent instructions (UCP discovery, an MCP endpoint, read-only JSON endpoints, policy links). It is not a curated index of your content. Then run one product URL through Google’s Rich Results Test.Review Agentic storefronts
In the admin, go to Sales channels > Agentic. Per Shopify Help, this is on by default for eligible stores, and it requires agreeing to the Agentic Storefronts Supplemental Terms. Shopify currently lists ChatGPT, Microsoft Copilot, Google AI Mode and Gemini, and Meta.
What each channel needs:
- ChatGPT: it is a discovery referrer. Shoppers finish checkout on your own store. Your store must sell to US customers, though it can be based elsewhere.
- Copilot and Google: both offer a Shopify-powered checkout inside the chat for eligible US stores, and both need your store policies completed. Google also needs a Merchant Center account, with products synced through the Google and YouTube channel.
- Shopify Catalog: per the requirements page, you need the Starter plan or higher and a store that is not in private mode. Each product needs a title, at least one image, a price above zero, and publication to a channel with a URL. Unlisted or search-hidden products do not qualify.
Use the search preview on that screen. It rates each listing on description completeness, image coverage, reviews, variant data and policies. Turning off ChatGPT Catalog access can take up to 7 days to take effect.
Fix your product data
This is where most of the gain is. Shopify’s Optimizing products for AI platforms page covers title, description, images, type, vendor, collections, tags, barcode, variant option names and policies. Items 1, 3, 4 and 9 below are our own recommendations, with sources where we have them:
- Title: specific, with product type, key attribute and brand. Keep the SEO title near 60 characters.
- Description: answer what buyers ask (materials, dimensions, who it is for, care).
- Images: several, each with descriptive alt text.
- Category: set under Products > (your product) > Category from the Standard Product Taxonomy, then fill the category metafields.
- Type, vendor, collections and tags: fill all four.
- Barcode: ISBN, UPC or GTIN on each variant that has one.
- Variant option names: “Size” and “Color”, not “Option 1”.
- Policies: refund, privacy, terms and shipping, completed.
- Reviews: the search preview counts them. The
structured_dataexample on shopify.dev shows noaggregateRating, so check the rendered JSON-LD from your reviews app. - Knowledge Base app (optional): you review auto-generated store facts and write FAQ answers for AI platforms. Shopify says those answers do not appear on your storefront and the app does not change how often you appear in AI results.
Customize llms.txt with a theme template (optional)
Go to Online Store > Themes > … > Edit code, then add a template in the
templatesfolder. Per the agents.md.liquid docs,agents.md.liquidcovers all three URLs, whilellms.txt.liquidcovers only that one. Shopify looks for the path-specific template, thenagents.md.liquid, then its own default.Only the
requestandagentsobjects exist in these templates. You cannot loop over collections or articles, so write your links by hand and keep them current. Keep the UCP and MCP lines dynamic throughagents.*rather than hardcoding them, and never output private data like emails or phone numbers.Redirects, Files and app proxies do not work for this file. URL redirects fire only on broken URLs, and
/llms.txtnow returns 200. Uploaded Files do not serve from the root. App proxies only work under/a,/apps,/communityand/tools. The template is the supported route.Treat this file as a courtesy for agents, not a ranking lever, since Google Search does not use llms.txt.
Touch robots.txt.liquid only if you must change access
Go to Online Store > Themes > … > Edit code > Add a new template > robots > Create template. Shopify calls this unsupported, Support cannot help with it, and it warns that a mistake can cost you all traffic. Copy your current
/robots.txtsomewhere first. Deleting the template restores the default.Keep Shopify’s default loop and add plain-text groups around it. The usual reason is opting out of model training, for example GPTBot. OpenAI documents that GPTBot and OAI-SearchBot are independent, so blocking GPTBot does not remove you from ChatGPT search.
Do not add
Allowgroups to welcome AI bots. See the first pitfall below.Leave Product markup to the theme and enrich the rest
Dawn 16.0.0 and Horizon already output
{{ product | structured_data }}and{{ article | structured_data }}. Do not add a second hand-written Product block. Two entities for one product conflict.To strengthen your Organization data, fill in the social links under Theme settings > Social media and upload a logo. In Dawn’s header those feed
sameAs, and empty settings render as empty strings. For a visible FAQ page, add thefaq-schema.liquidsection below, using the| jsonfilter, and only for questions that are on the page.Publish content that answers buyer questions
Write buying guides and comparisons under Content > Blog posts and link them to products and collections. Give each collection a real description with its own SEO title (Shopify recommends up to 60 characters) and a description of about 160. Put a visible FAQ on a page under Online Store > Pages, then link it from your
llms.txt.liquid.Check it workedCheck it worked
Run these from a terminal, replacing the domain and product handle:
curl -sI https://yourstore.com/llms.txt | head -n 5should show 200, and a GET should show your edited content.curl -s https://yourstore.com/llms.txt | head -n 20should show your headings and links.curl -sI https://yourstore.com/agents.mdandcurl -sI https://yourstore.com/sitemap.xmlshould both return 200.curl -s https://yourstore.com/robots.txtshould still contain the cart and checkout disallows under*.curl -s https://yourstore.com/products/your-handle | grep -oE '"@type" ?: ?"(Product|ProductGroup)"' | sort | uniq -cshould show one entity.Re-check the Agentic search preview afterward.
Shopify code
Your templates/llms.txt.liquid. Replace the placeholder text and the page paths with your own:
# {{ agents.store_name }}

> Short, factual summary of what the store sells, who it is for, and where it ships.

## Key pages
- [All products]({{ agents.store_url }}/collections/all)
- [Best sellers]({{ agents.store_url }}/collections/best-sellers): our most ordered products
- [Size and fit guide]({{ agents.store_url }}/pages/size-guide)
- [FAQ]({{ agents.store_url }}/pages/faq): shipping, returns, care
- [Buying guides]({{ agents.store_url }}/blogs/guides)

## Policies
- [Refund policy]({{ agents.store_url }}/policies/refund-policy)
- [Shipping policy]({{ agents.store_url }}/policies/shipping-policy)

## For agents
- UCP discovery: {{ agents.ucp_discovery_url }}
- MCP endpoint: {{ agents.mcp_endpoint_url }}
- Sitemap: {{ agents.sitemap_url }}
- Prices are in {{ agents.currency }}.
The robots.txt.liquid below keeps Shopify’s default loop and adds one training opt-out. Per shopify.dev, plain-text groups for a new crawler go outside the loop:
{% for group in robots.default_groups %}
{{- group.user_agent }}
{%- for rule in group.rules -%}
  {{ rule }}
{%- endfor -%}
{%- if group.sitemap != blank -%}
  {{ group.sitemap }}
{%- endif -%}
{% endfor %}

User-agent: GPTBot
Disallow: /
The theme’s own structured data pattern. This is already in Dawn, so you only need it if you build a custom theme:
<script type="application/ld+json">
{{ product | structured_data }}
</script>

<script type="application/ld+json">
{{ article | structured_data }}
</script>
The Organization block from Dawn 16.0.0 sections/header.liquid, verbatim from Shopify/dawn. It is a reference, so you do not need to paste it into a stock Dawn theme:
<script type="application/ld+json">
{
  "@context": "http://schema.org",
  "@type": "Organization",
  "name": {{ shop.name | json }},
  {% if settings.logo %}
    "logo": {{ settings.logo | image_url: width: 500 | prepend: "https:" | json }},
  {% endif %}
  "sameAs": [
    {{ settings.social_twitter_link | json }},
    {{ settings.social_facebook_link | json }},
    {{ settings.social_pinterest_link | json }},
    {{ settings.social_instagram_link | json }},
    {{ settings.social_tiktok_link | json }},
    {{ settings.social_tumblr_link | json }},
    {{ settings.social_snapchat_link | json }},
    {{ settings.social_youtube_link | json }},
    {{ settings.social_vimeo_link | json }}
  ],
  "url": {{ request.origin | append: page.url | json }}
}
</script>
A manual FAQPage section for a visible FAQ page. The question text is a placeholder: replace it with the exact Q&A shown on the page.
{%- comment -%} Add to the FAQ page template only {%- endcomment -%}
<script type="application/ld+json">
{
"@context": "https://schema.org",
"@type": "FAQPage",
"mainEntity": [
  {
    "@type": "Question",
    "name": {{ "How long does shipping take?" | json }},
    "acceptedAnswer": {
      "@type": "Answer",
      "text": {{ "Orders ship in 1 to 2 business days. US delivery takes 3 to 5 days." | json }}
    }
  }
]
}
</script>
Google removed the FAQ rich result, so do not add this expecting stars or expandable snippets. The markup still describes the page accurately to any parser that reads it.
llms.txt.liquid
Dynamic llms.txt template for a Shopify theme.
Shopify
robots.txt.liquid
Default loop kept, plus a training opt-out.
Shopify
FAQ schema section
FAQPage JSON-LD for a visible FAQ page.
Shopify
React, Next.js and Astro: step-by-step
Custom stacks have one failure that matters more than any file you add: the answer is missing from the HTML the server sends. Check that first, in any framework, with one test. Fetch the page the way a crawler that does not run JavaScript does, and look for a sentence from the body.
Check whether the answer is in the server HTML before anything else. The Vercel and MERJ study found that several major AI crawlers did not render JavaScript, and Vercel’s 2026 follow-up found a fetch-only client could not get an answer that existed only through JavaScript. Dates and details are in the server HTML foundation. Google says server-side or pre-rendering is still a great idea, and calls dynamic rendering a workaround, not a long-term solution.
#!/usr/bin/env bash
# Usage: ./check-ai-crawl.sh https://www.example.com/your-page "a sentence from the page"
# Fetches the page the way a crawler that does not run JavaScript sees it.
# This only tests user-agent rules. Firewalls that verify crawler IPs will treat
# your request as an impostor, so confirm with server logs as well.
URL="$1"; PHRASE="$2"
UA='Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; GPTBot/1.4; +https://openai.com/gptbot'
HTML=$(curl -sL -A "$UA" "$URL")
HEAD=${HTML%%</head>*}
echo "Status:        $(curl -s -o /dev/null -w '%{http_code}' -A "$UA" "$URL")"
echo "Redirects to:  $(curl -s -o /dev/null -w '%{redirect_url}' -A "$UA" "$URL")"
echo "Title in head: $(grep -o '<title>[^<]*' <<<"$HEAD" | sed 's/<title>//' | head -1)"
echo "Canonical:     $(grep -o '<link rel="canonical"[^>]*' <<<"$HEAD" | grep -o 'href="[^"]*' | sed 's/href="//' | head -1)"
echo "JSON-LD blocks: $(grep -o 'application/ld+json' <<<"$HTML" | wc -l | tr -d ' ')"
if grep -qF "$PHRASE" <<<"$HTML"; then echo "Phrase in raw HTML: YES"; else echo "Phrase in raw HTML: NO (content likely needs JavaScript)"; fi
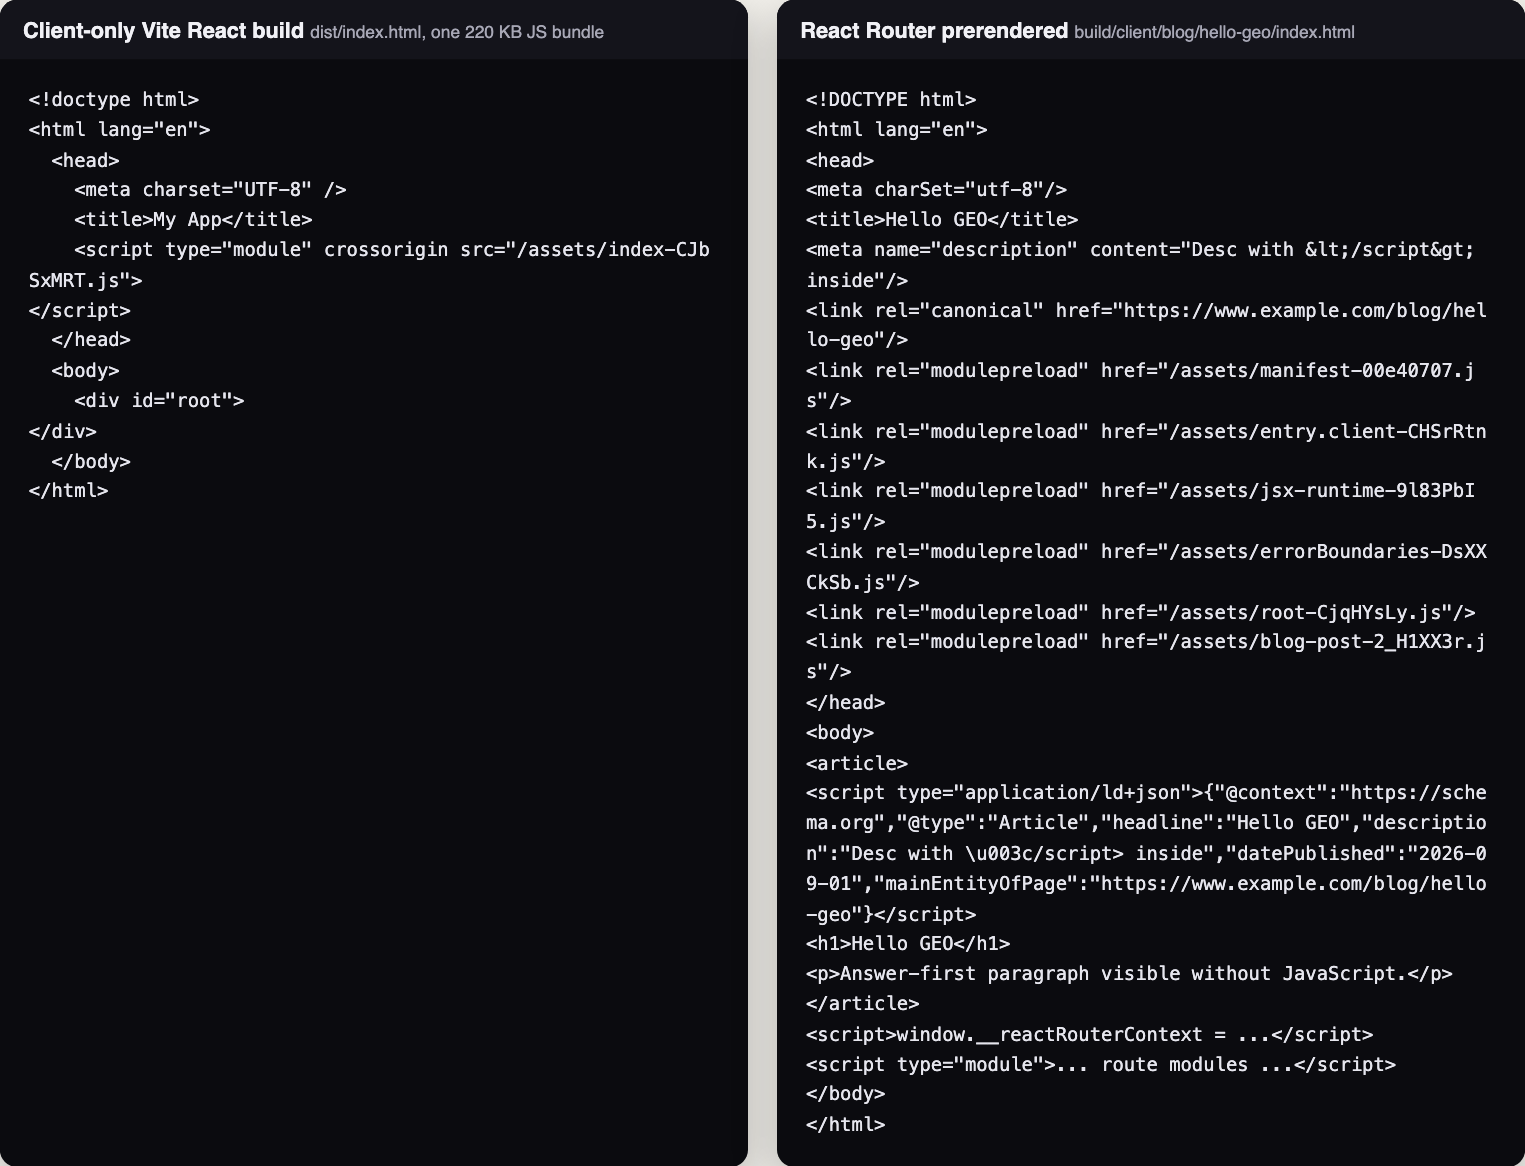
We ran it on two builds of the same article. The client-only Vite app returned an empty div id="root", the title “My App” and no JSON-LD. The text lived in a 220 KB JavaScript bundle. The same content prerendered with React Router returned the real title, the canonical, the JSON-LD and the phrase.
React SEO for AI crawlers: prerender the HTML
A client-rendered React app can rank in Google and still be empty to other crawlers, because Googlebot renders JavaScript. Testing only in Google hides the problem.
StepsMake a React SPA readable without JavaScript
Diagnose with view-source
Open your key page, choose View Source (not DevTools) and look for your headline. An empty
div id="root"means non-rendering crawlers get nothing. Then runcheck-ai-crawl.shabove and look for “Phrase in raw HTML: YES”.Pick a fix, in this order
- React Router framework mode with
prerenderandssr: false. Its docs say pre-rendering is useful for SEO, especially for deployments without server rendering. - Move to Next.js, covered next.
- For a content-heavy marketing site, Astro with React islands.
- A custom prerender with
react-dom/static. It works but is low-level, and frameworks normally call it for you.
Skip dynamic rendering. Create React App has been deprecated for new apps since February 14, 2025. Check the React Router docs for the version you have installed, since prerender options are documented per version.
- React Router framework mode with
Prerender every content URL, slugs included
prerender: trueskips dynamic paths such as/blog/:slug. Use the function form and add the slugs yourself.react-router.config.ts import type { Config } from '@react-router/dev/config' import { getPostSlugs } from './app/lib/posts' export default { // No runtime server: every listed URL becomes a static HTML file at build time. ssr: false, async prerender({ getStaticPaths }) { const slugs = await getPostSlugs() return [...getStaticPaths(), ...slugs.map((s) => '/blog/' + s)] }, } satisfies ConfigPut head tags in the route component
React Router recommends the built-in
title,metaandlinkelements over the route module’smetaexport. React 19 hoists them into the document head. In our build they landed inheadof the prerendered file. Add JSON-LD in the same component and escape<, becauseJSON.stringifyleaves</script>intact.app/routes/blog-post.tsx import { data, useLoaderData } from 'react-router' import { getPost } from '../lib/posts' const SITE_URL = 'https://www.example.com' // With prerendering, this loader runs at build time, so the post is in the HTML file. export async function loader({ params }: { params: { slug?: string } }) { const post = await getPost(params.slug ?? '') if (!post) throw data('Not found', { status: 404 }) return { post } } export default function BlogPost() { const { post } = useLoaderData<typeof loader>() const url = SITE_URL + '/blog/' + post.slug const article = { '@context': 'https://schema.org', '@type': 'Article', headline: post.title, description: post.description, datePublished: post.publishedAt, mainEntityOfPage: url, } return ( <article> <title>{post.title}</title> <meta name="description" content={post.description} /> <link rel="canonical" href={url} /> <script type="application/ld+json" dangerouslySetInnerHTML={{ __html: JSON.stringify(article).replace(/</g, '\u003c') }} /> <h1>{post.title}</h1> <p>{post.body}</p> </article> ) }Deploy with a narrow fallback
Serve
build/client. Rewrite only paths you did not prerender to__spa-fallback.html. That rewrite answers 200 for every unknown URL, so keep your sitemap exact. In its 2024 data Vercel saw ChatGPT’s crawler spend a large share of fetches on 404s, so broken or stray URLs cost you.Check it workedCheck it worked
The build log should print a line like
Prerender (html): /blog/hello-geo -> build/client/blog/hello-geo/index.html. Open that file, confirm the title, canonical and article text are in it, then runcheck-ai-crawl.shagainst the deployed URL. You wantPhrase in raw HTML: YES.
react-router.config.ts
Prerender config with dynamic slugs.
React
Blog post route
Head tags and escaped JSON-LD in the route component.
React
Next.js SEO and llms.txt (App Router)
Next.js can send full HTML, but it is easy to build a page that does not. These steps were built and tested on Next.js 16.4.0 (the docs are for the same version).
StepsShip answer text and metadata in the first response
Keep answer text in Server Components
Pages and layouts are Server Components by default. Client Components are prerendered too, but data loaded in
useEffectis not in that HTML. In our 16.4.0 test, a'use client'page that loaded its text in an effect shipped HTML containing only “Loading…”. Use Client Components for interactivity, not for the answer.Set root metadata with metadataBase
In
app/layout.tsx, exportmetadatawithmetadataBase: new URL(SITE_URL), a title template,alternates.canonicalandopenGraph. Metadata exports only work in Server Components.Use generateMetadata and generateStaticParams
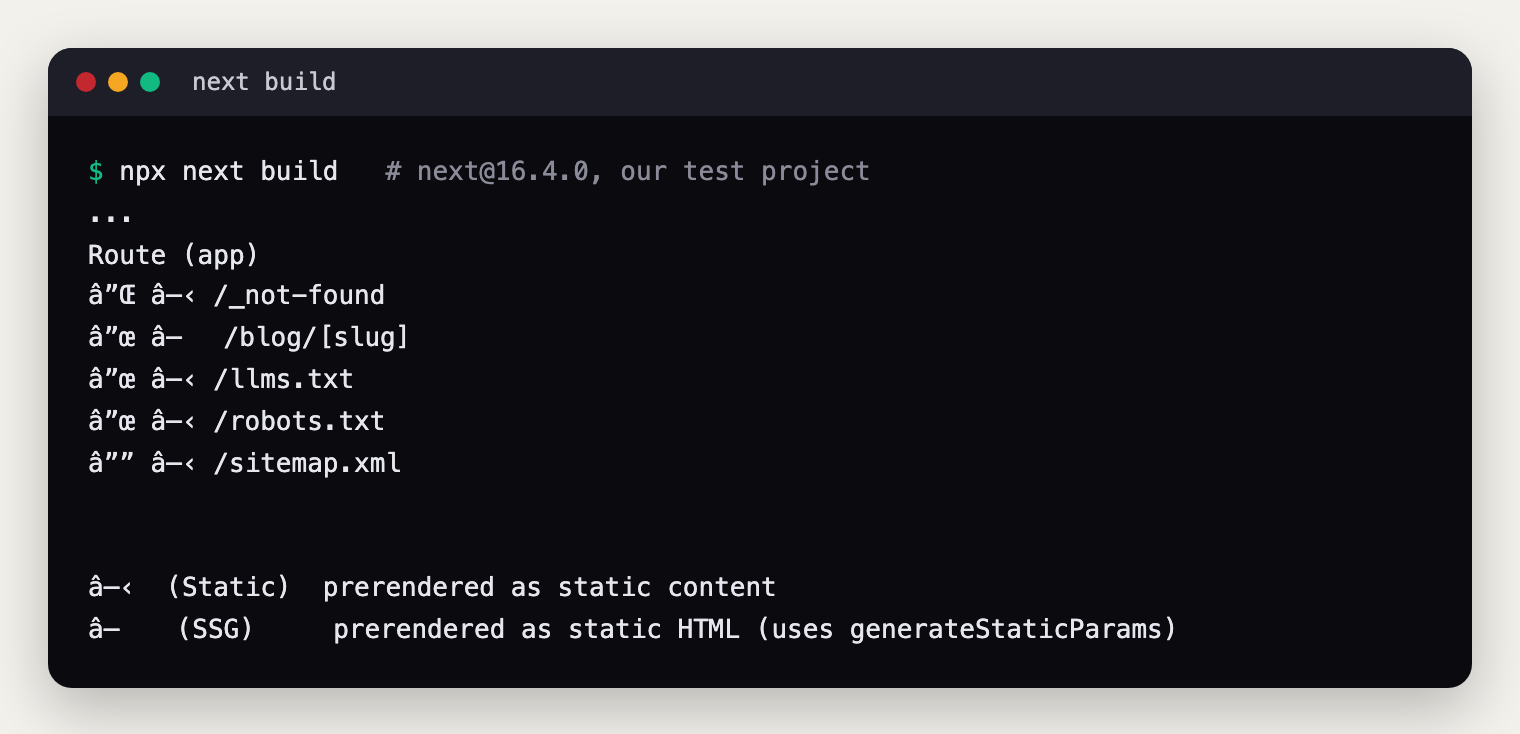
paramsis a Promise in current versions. Prerendering posts means the metadata and the full article are in the initial HTML, and the route shows as SSG in the build table.app/blog/[slug]/page.tsx import type { Metadata } from 'next' import { notFound } from 'next/navigation' import { getPost, getPosts } from '@/lib/posts' import { SITE_URL } from '@/lib/site' import { jsonLd } from '@/lib/json-ld' type Props = { params: Promise<{ slug: string }> } // Prerender every post at build time so the full article is in the HTML response. export async function generateStaticParams() { return (await getPosts()).map((p) => ({ slug: p.slug })) } export async function generateMetadata({ params }: Props): Promise<Metadata> { const { slug } = await params const post = await getPost(slug) if (!post) return {} return { title: post.title, description: post.description, alternates: { canonical: '/blog/' + post.slug }, } } export default async function Page({ params }: Props) { const { slug } = await params const post = await getPost(slug) if (!post) notFound() const article = { '@context': 'https://schema.org', '@type': 'Article', headline: post.title, datePublished: post.publishedAt, dateModified: post.updatedAt ?? post.publishedAt, mainEntityOfPage: SITE_URL + '/blog/' + post.slug, } return ( <article> <script type="application/ld+json" dangerouslySetInnerHTML={{ __html: jsonLd(article) }} /> <h1>{post.title}</h1> <div>{post.body}</div> </article> ) }Render JSON-LD as a native script, escaped
The Next.js JSON-LD guide says to use a plain
scripttag, notnext/script, and to replace<with its unicode escape becauseJSON.stringifydoes not sanitize. Put that in one helper.lib/json-ld.ts // JSON.stringify does not escape "<", so "</script>" inside a value would end the tag early. export function jsonLd(data: object): string { return JSON.stringify(data).replace(/</g, '\u003c') }Write robots.ts with repeated disallows
app/robots.tsaccepts an array foruserAgent. A crawler obeys only its most specific matching group, so repeat the disallows. Treat training crawlers as a separate decision from search bots.app/robots.ts import type { MetadataRoute } from 'next' import { SITE_URL } from '@/lib/site' export default function robots(): MetadataRoute.Robots { return { rules: [ { userAgent: '*', allow: '/', disallow: ['/api/', '/account/'] }, { userAgent: [ 'OAI-SearchBot', 'ChatGPT-User', 'Claude-SearchBot', 'Claude-User', 'PerplexityBot', 'Perplexity-User', 'GPTBot', 'ClaudeBot', 'Google-Extended', ], allow: '/', disallow: ['/api/', '/account/'], }, ], sitemap: SITE_URL + '/sitemap.xml', } }Write sitemap.ts with real lastModified
Google ignores priority and changefreq and uses lastmod only when it is consistently accurate. Take the date from the content, never
new Date().app/sitemap.ts import type { MetadataRoute } from 'next' import { getPosts } from '@/lib/posts' import { SITE_URL } from '@/lib/site' export default async function sitemap(): Promise<MetadataRoute.Sitemap> { const posts = await getPosts() return [ { url: SITE_URL, lastModified: '2026-10-01' }, ...posts.map((p) => ({ url: SITE_URL + '/blog/' + p.slug, lastModified: p.updatedAt ?? p.publishedAt, })), ] }Serve llms.txt from a route handler
GET Route Handlers are not cached by default, so add
force-static. If you enablecacheComponents, delete that line: the option is removed in that mode, and a handler that reads no request data is prerendered. Build the list from the same posts function the pages use.app/llms.txt/route.ts import { getPosts } from '@/lib/posts' import { SITE_NAME, SITE_URL } from '@/lib/site' // Delete this line if cacheComponents is enabled. export const dynamic = 'force-static' export async function GET() { const posts = await getPosts() const body = [ '# ' + SITE_NAME, '', '> One or two sentences: what you do, for whom, and where.', '', '## Guides', ...posts.map((p) => '- [' + p.title + '](' + SITE_URL + '/blog/' + p.slug + '): ' + p.description), '', ].join('\n') return new Response(body, { headers: { 'Content-Type': 'text/plain; charset=utf-8' } }) }The same caveat as before applies: this file is a supplement to server HTML, not a substitute for it.
Handle request-time routes: the htmlLimitedBots trap
Routes that read cookies, headers or uncached data render at request time. Since Next.js 15.2, their
generateMetadataoutput streams intobodyfor any bot not on the HTML-limited list. We read the default list in the source and it has no AI crawlers. In our 16.4.0 test, GPTBot and ClaudeBot got thetitleinbodyby default and inheadafter we added them.Setting the option replaces the default list, so copy the default and append the AI bots. Re-check the copy on every Next.js upgrade. Fully prerendered pages are not affected. The Next.js docs say streaming does not hurt SEO; that statement is about Google, which runs JavaScript, so do not stretch it to AI crawlers.
next.config.ts import type { NextConfig } from 'next' // Copied from the Next.js default (canary html-bots.ts, October 2026). Re-check on upgrade. const NEXT_DEFAULT = String.raw`[\w-]+-Google|Google-[\w-]+|Chrome-Lighthouse|Slurp|DuckDuckBot|baiduspider|yandex|sogou|bitlybot|tumblr|vkShare|quora link preview|redditbot|ia_archiver|Bingbot|BingPreview|applebot|facebookexternalhit|facebookcatalog|Twitterbot|LinkedInBot|Slackbot|Discordbot|WhatsApp|SkypeUriPreview|Yeti|googleweblight` const AI_CRAWLERS = 'GPTBot|OAI-SearchBot|ChatGPT-User|ClaudeBot|Claude-SearchBot|Claude-User|PerplexityBot|Perplexity-User' const nextConfig: NextConfig = { htmlLimitedBots: new RegExp(NEXT_DEFAULT + '|' + AI_CRAWLERS, 'i'), } export default nextConfigDecide whether you need static export
With
output: 'export', Next.js writes HTML toout/and Route Handlers must beforce-staticto be prerendered. That suits a brochure site hosted on plain storage.Check it workedCheck it worked
In the
next buildroute table your content routes should show as static or SSG, not as dynamic. Then fetch/robots.txt,/sitemap.xmland/llms.txt(the last should returntext/plain; charset=utf-8) and runcheck-ai-crawl.shon one post. An unknown slug should return 404.
App Router metadata and JSON-LD
generateMetadata, generateStaticParams and a native JSON-LD script.
Next.js
robots, sitemap and llms.txt
robots.ts with repeated disallows. The sitemap and llms.txt route files are in the same folder.
Next.js
next.config.ts
htmlLimitedBots with the AI crawlers appended.
Next.js
Astro SEO and llms.txt
Astro is the easiest of the three, because pages and endpoints are pre-rendered at build time by default. Most of the work is avoiding mistakes.
StepsAdd AI-readable files to an Astro site
Keep answer text out of client:only
Components without a
client:*directive render to plain HTML.client:onlyskips server rendering entirely, so never put answer text in one.Add a JSON-LD component that escapes
set:htmlis not escaped by Astro, andJSON.stringifyleaves</script>alone. In our Astro 7.0.5 test, a description containing</script>ended the block early and it failed JSON parsing. Escaping<fixed it. Astro does not process a script tag that has attributes other thansrc, so the block is output as written.src/components/JsonLd.astro --- interface Props { data: Record<string, unknown>; } const { data } = Astro.props; const json = JSON.stringify(data).replace(/</g, '\u003c'); --- <script type="application/ld+json" set:html={json} />Generate llms.txt from the content collection
A static file endpoint at
src/pages/llms.txt.tsbuilds/llms.txtat build time. Reading fromgetCollection()means it cannot drift from the published pages.src/pages/llms.txt.ts import type { APIRoute } from 'astro'; import { getCollection } from 'astro:content'; export const GET: APIRoute = async ({ site }) => { const url = (path: string) => new URL(path, site).href; const posts = (await getCollection('blog', ({ data }) => !data.draft)).sort( (a, b) => b.data.publishDate.getTime() - a.data.publishDate.getTime(), ); const body = [ '# Example Co', '', '> One or two sentences: what you do, for whom, and where.', '', '## Guides', ...posts.map((p) => '- [' + p.data.title + '](' + url('/blog/' + p.id) + '): ' + p.data.description), '', ].join('\n'); return new Response(body, { headers: { 'Content-Type': 'text/plain; charset=utf-8' } }); };Choose one source for robots.txt
Use
public/robots.txtor an endpoint, not both. The endpoint can reusesiteand repeat the rules in the AI group, as the sitemap integration docs show for sitemaps.src/pages/robots.txt.tsUse this OR public/robots.txt import type { APIRoute } from 'astro'; const AI_AGENTS = [ 'OAI-SearchBot', 'ChatGPT-User', 'Claude-SearchBot', 'Claude-User', 'PerplexityBot', 'Perplexity-User', 'GPTBot', 'ClaudeBot', 'Google-Extended', ]; export const GET: APIRoute = ({ site }) => { const sitemapURL = new URL('sitemap-index.xml', site); const rules = 'Allow: /\nDisallow: /api/'; return new Response( [ 'User-agent: *\n' + rules, // A crawler that matches a named group ignores the * group, so repeat the rules. AI_AGENTS.map((ua) => 'User-agent: ' + ua).join('\n') + '\n' + rules, 'Sitemap: ' + sitemapURL.href, '', ].join('\n\n'), ); };Set sitemap lastmod from frontmatter, for .md and .mdx
@astrojs/sitemapneeds thesiteoption and cannot list SSR dynamic routes. Useserialize()to setlastmodfrom each post. Match both extensions, or converting a post to MDX silently drops its date. We found this on our own site.astro.config.mjs import { defineConfig } from 'astro/config'; import sitemap from '@astrojs/sitemap'; import { readdirSync, readFileSync } from 'node:fs'; const postDates = Object.fromEntries( readdirSync('./src/content/blog') .filter((f) => /\.mdx?$/.test(f)) .map((f) => { const fm = readFileSync('./src/content/blog/' + f, 'utf8').split('---')[1] ?? ''; const date = fm.match(/^updatedDate:\s*(\S+)/m)?.[1] ?? fm.match(/^publishDate:\s*(\S+)/m)?.[1]; return ['/blog/' + f.replace(/\.mdx?$/, ''), date]; }), ); export default defineConfig({ site: 'https://www.example.com', integrations: [ sitemap({ serialize(item) { const path = new URL(item.url).pathname.replace(/\/$/, ''); const date = postDates[path]; if (date) item.lastmod = new Date(date).toISOString(); return item; }, }), ], });Link the file so agents find it
Add
link rel="alternate" type="text/plain" href="/llms.txt"or a footer link. The llms.txt v2 spec usesrel="describedby"for this.Check it workedCheck it worked
Run
npx astro build. Opendist/llms.txt,dist/robots.txt,dist/sitemap-0.xmland onedist/blog/your-post/index.html. After deploy, runcheck-ai-crawl.shon the live URL and look for “Phrase in raw HTML: YES”.
JsonLd.astro
JSON-LD component that escapes the less-than sign.
Astro
llms.txt endpoint
Builds llms.txt from the content collection.
Astro
robots.txt endpoint
Repeats the rules inside the AI group.
Astro
Sitemap serializer
Sets lastmod from frontmatter for .md and .mdx.
Astro
maxenius.com as a live Astro example
This site is built the way the steps above describe, and you can inspect it.
src/lib/llms.ts,src/pages/llms.txt.tsandsrc/pages/llms-full.txt.tsbuild /llms.txt and /llms-full.txt from the same data as the pages.public/robots.txtrepeats its rules inside the named AI-crawler group. That is a maximum-visibility policy: it welcomes every listed crawler, training crawlers included. Choose your own policy deliberately, as covered in the robots.txt foundation.Seo.astroandsrc/lib/seo.tsoutput a robots meta tag withmax-snippet:-1, alink rel="alternate" type="text/plain"to/llms.txt, and a JSON-LD graph of Organization, WebSite, WebPage, Article, FAQPage and BreadcrumbList.astro.config.mjsuses static output and takes sitemaplastmodfrom each post’s frontmatter.
Whatever you choose, server HTML is the foundation. The files and markup in this section are supplements on top of it.
Measure and test
You need five sources, because none of them covers everything: Search Console for Google, GA4 or Plausible for clicks, Bing Webmaster Tools for Copilot citations, server logs for bots, and prompt tests for what the answers say. Each one answers a different question and has blind spots, so read them side by side.
Where each source reports
| Source | What it shows | What it does not show |
|---|---|---|
| Search Console Performance | AI Overview and AI Mode clicks and impressions, counted inside the Web search type. A click on an external link in either feature counts. | Every link in an AI Overview shares one position, so a cited page can show a good position and a tiny CTR. An AI Mode follow-up counts as a new query. Search Labs experiments are excluded. Google’s AI features page confirms the Web type. |
| Search Console Generative AI report | Impressions in AI Overviews and AI Mode by page, country, device and date. Announced June 3, 2026; all sites since August 31, 2026. | No clicks, CTR, position or queries. It may not appear if your site has too few AI impressions. It is a subset of Web data, so do not add it to the Performance report. |
| Bing Webmaster Tools AI Performance | Public preview since February 10, 2026: Total Citations, Average Cited Pages, grounding queries (sampled) and page-level citation activity. Since June 16, 2026: Intents, Topics, Citation Share and Compare, in preview. | A citation is not a click or a visit. Data is sampled, and grounding queries are grouped phrases, not real prompts. Citation Share does not expose competitor domains. |
| GA4 and Plausible | Visits with a referrer or UTM. GA4 has had an AI Assistant default channel since May 13, 2026. Plausible has an AI Assistants channel. | The GA4 channel excludes AI Overviews and AI Mode, which count as Organic Search. OpenAI documents only utm_source=chatgpt.com, so other assistants depend on referrers. |
| Server logs | Every bot request, including user-triggered fetches that never run JavaScript. | Who read the answer or clicked. Needs IP checks, because user agents can be faked. |
| Prompt tests | What each engine actually says about you today. | A stable rank. Google says AI Overviews and AI Mode may use different models and vary their links, so single runs mislead. |
Set up measurement, step by step
StepsMeasure AI search visibility
Separate impressions from AI features
Start here for any page with high impressions and almost no clicks.
- In Search Console, open Performance, filter Page to your URL, and note impressions, clicks, CTR and average position.
- Open the Generative AI performance report, go to the Pages tab, and find the same URL.
- Compare the two impression counts. The AI report is a subset of Web, so never add them. If AI features account for most impressions, a good position with a low CTR is expected, because all links in an AI Overview share one position.
- If the report is missing, Google says the site has not had enough AI impressions yet. That is not an error.
- Open Settings > Search generative AI and confirm the property is not set to Exclude and is not inheriting Exclude from a parent. See Search generative AI control.
- Add an annotation on the day you ship changes: right-click the Performance chart, up to 120 characters (annotations help).
Use the built-in AI Assistant channel
In GA4, go to Reports > Acquisition > Traffic acquisition. Set the primary dimension to Session default channel group and look for the AI Assistant row. Add Session source as a secondary dimension to see which assistant sent each session. Clicks from AI Overviews and AI Mode will not be here. In Plausible, open Sources > Channels > AI Assistants.
Add a custom channel group
Go to Admin > Data display > Channel groups, create a group, and add a channel where Source matches the regex below. Drag it above Referral, because traffic goes to the first channel it matches. Standard properties allow 2 custom groups, and custom groups are not in the BigQuery export.
Google’s own sample regex in that help article over-matched in our test: it also caught help.openai.com, github.com/copilot, chatgptlist.org and “shanghai”. Use this narrower one instead.
ga4-ai-sources.regex111 characters, anchored ^(.*\.)?(chatgpt\.com|chat\.openai\.com|perplexity\.ai|claude\.ai|copilot\.microsoft\.com|gemini\.google\.com)$It accepts chatgpt.com, chat.openai.com, www.perplexity.ai, claude.ai, copilot.microsoft.com and gemini.google.com. It rejects google, mail.google.com, openai.com, help.openai.com, notchatgpt.com, perplexity.ai.evil.com and bing.com. It covers the www host and the old ChatGPT host because chat.openai.com redirects to chatgpt.com and perplexity.ai redirects to www.perplexity.ai. GA4 regex is full-match and case-sensitive by default, uses RE2, and report filters cap at 250 characters. The anchors keep this pattern correct in both match modes. Add other assistants only after they show up in your own Session source report.
Watch for lost UTMs
Look in Session source / medium for chatgpt.com rows sitting in Unassigned or Referral, because Google does not document how GA4 resolves a utm_source with no medium against the AI Assistant rule. A redirect that drops the query string, such as a trailing-slash, www or http-to-https rule, also drops the UTM. Test a tagged URL through every redirect you run.
Build an Exploration (optional)
Skip this if the built-in channel report answers your question. In Explore, start a blank exploration. Import the dimensions Session source, Session source / medium, Landing page + query string and Session default channel group, plus the metrics Sessions, Engaged sessions and Key events. Put Session source and then Landing page + query string in Rows, and filter Session source with the same regex.
Read Copilot and Bing citations
- Verify the site in Bing Webmaster Tools and open the AI Performance report.
- Read Total Citations, Average Cited Pages, grounding queries and the Pages list. Click a grounding query to see its cited pages, or a page to see its grounding queries.
- Use Compare to overlay the period after you shipped changes. Intents, Topics and Citation Share are preview features.
- Export CSV or Excel monthly. Read the FAQ for the sampling and refresh rules.
- Submit changed URLs through IndexNow. Bing recommends it so AI answers use the current page version.
Count AI bot hits in server logs
Look for these user agents. Search: OAI-SearchBot, Claude-SearchBot, PerplexityBot, Googlebot, bingbot. Training: GPTBot, ClaudeBot. User-triggered: ChatGPT-User, Claude-User, Perplexity-User. Google-Extended will never appear, because it is a robots.txt token with no user agent of its own.
User-triggered hits matter most. Each one means a real conversation read your page, and because these fetches do not run JavaScript, GA4 and Plausible never see them.
A quick count from a combined-format log. This awk version counts each line once, where a plain grep counted bingbot twice per line:
terminalCounts each line once awk 'match($0, /OAI-SearchBot|ChatGPT-User|GPTBot|Claude-SearchBot|Claude-User|ClaudeBot|PerplexityBot|Perplexity-User|Googlebot|bingbot/) { print substr($0, RSTART, RLENGTH), $7 }' access.log | sort | uniq -c | sort -rnUser agents are easy to fake, so verify IPs. Our
ai_bot_report.py(Python 3, standard library only, in the kit) counts hits per day, bot, status and path, and checks each IP against the operator’s published list for OpenAI, Anthropic, Perplexity, Google and Bing. A row withip_verified=NOis a spoofed user agent. It flags a fake GPTBot from an unlisted IP.terminal python3 ai_bot_report.py access.log > ai-bots.csv zcat access.log.*.gz | python3 ai_bot_report.py - > ai-bots.csvWithout the script, use the double lookup: reverse DNS on the IP must return a Google hostname (googlebot.com, google.com or googleusercontent.com) or one ending in search.msn.com for Bingbot, and a forward lookup of that name must return the same IP.
On Vercel, go to Firewall > Rules > Bot Management and set the AI Bots ruleset to Log, not Deny (WAF managed rulesets). Then use Firewall > Traffic and group by User Agents and Request Paths (observability). Runtime Logs show only static requests served from cache. A full log needs Drains, which are on Pro and Enterprise plans, with
proxy.userAgentin each record:vercel-drain-bots.shNeeds jq jq -r 'select(.proxy) | [(.proxy.timestamp/1000|todate), .proxy.clientIp, .proxy.path, (.proxy.statusCode|tostring), (.proxy.userAgent|join(" "))] | @tsv' drain.ndjson \ | awk -F'\t' 'match($5, /OAI-SearchBot|ChatGPT-User|GPTBot|Claude-SearchBot|Claude-User|ClaudeBot|PerplexityBot|Perplexity-User|Googlebot|bingbot/) { print substr($5, RSTART, RLENGTH) "\t" $3 }' \ | sort | uniq -c | sort -rnOn Cloudflare, open AI Crawl Control. If AI crawler hits are near zero, check whether the managed robots.txt setting is prepending Disallow rules for GPTBot, ClaudeBot or Google-Extended.
Run a repeatable prompt test
No official tool reports ChatGPT, Claude or Perplexity citations, so test by hand with a fixed protocol.
- Write 20 to 40 prompts across how-to, comparison, platform-specific and two or three brand questions. Give each a permanent ID. To change wording, retire the ID and add a new one.
- Engines: ChatGPT with search on, Google AI Mode, Google AI Overviews (a normal search), Gemini, Perplexity, Microsoft Copilot, Claude with web search on.
- Hold settings constant: country, language, signed in or out. In ChatGPT use Temporary chat set to Unpersonalized, which skips memory and custom instructions. Personalized can still use existing memories. Elsewhere, use a fresh profile or signed-out session and note the mode or model.
- Run each prompt 3 times per engine. Answers vary between runs.
- Cadence: a monthly baseline, plus one rerun 2 to 4 weeks after a major content change.
- Log every run in
ai-prompt-tracker.csv(26 columns, two clearly labeled example rows). Compute mention rate, citation rate and citation share (your cited URLs divided by all cited URLs, the same idea as Bing’s metric). - Keep screenshots as private evidence. Do not publish third-party interfaces.
Google Sheets or ExcelData on a sheet named runs Mention rate =COUNTIF(runs!N2:N1000,"yes")/COUNTA(runs!C2:C1000) Citation rate =COUNTIF(runs!P2:P1000,"yes")/COUNTA(runs!C2:C1000) Citation share =SUM(runs!R2:R1000)/SUM(runs!S2:S1000)Check it workedCheck it worked
Confirm four things:
- You have a before figure for the URL (total impressions and AI-feature impressions) and an annotation dated on the ship day.
- The GA4 filter returns only assistant hosts.
- The bot output shows your own requests. Make one with
curl -A 'OAI-SearchBot' -s -o /dev/null https://yourdomain.com/robots.txt, then look for a row with that bot name and status 200. - The prompt tracker has a baseline row for every prompt ID and engine.
If you would rather have the measurement set up and read for you, see our AI SEO services.
Third-party tools
Ahrefs Brand Radar tracks mentions and citations across AI Overviews, AI Mode, ChatGPT, Gemini, Perplexity and Copilot, using a prompt index Ahrefs says is modeled from search data, plus custom prompts you choose. The Semrush AI Visibility Toolkit offers a visibility score, prompt research and daily prompt tracking. Cloudflare AI Crawl Control reports crawler activity for sites behind Cloudflare. These tools sample prompts rather than reading real user conversations, and Google says no third-party tool has access to its AI ranking systems. Treat their numbers as directional and compare them against your own first-party data.
Self-audit checklist
Work through this list on your own site. Each item links back to the section that explains it. Your progress is saved in this browser only, so it will not follow you to another device.
GEO self-audit
0 of 33 done
GEO starter kit
Everything in this guide that you can copy is in one free download, with no signup and no email form.
Download the full GEO starter kit
53 files in one archive: robots.txt, llms.txt, JSON-LD, IndexNow, WordPress, Shopify, Next.js, React, Astro, scripts, a prompt tracker and a content brief.
Any
Printable self-audit checklist
The checklist above, two A4 pages, ready to print or save.
Any
Prompt tracker
The 26-column tracker. Formulas and the test protocol are in the same folder.
Any
Content brief template
An answer-first content brief.
Any
Bot report script
Counts AI bot hits from a log and checks each IP against published ranges.
Any
GA4 AI sources regex
The narrower regex for a custom channel group.
Any
HTML head snippet
Robots meta and data-nosnippet markup.
Any
IndexNow ping
A batch ping command, with a key file example in the same folder.
Any
The platform files are linked in each platform section above. Every file uses placeholders such as example.com, sample keys and sample names. Replace each one before you deploy, and run the check step from the matching section.
Next steps
Start with the self-audit checklist above and fix the first failed item, usually bot access or server HTML. If you would rather have the work done and verified on your own site, Maxenius runs AI SEO and GEO audits and implementation. We check crawler access, rendering, structured data and measurement against the steps in this guide, and we report what changed with evidence. No one can guarantee AI citations, so we do not offer that.
Book an AI search auditIf the work is a build, we also do Shopify development, WordPress development and custom software development. Vendor documentation changes often. Recheck the sources below monthly.
Sources and dates
All opened and checked October 7, 2026.
- Google Search Console Help, What are impressions, position, and clicks
- Google Search Console Help, Generative AI performance report
- Google Search Console Help, Search generative AI control
- Google Search Console Help, Search Console annotations
- Google Search Central Blog, Introducing Search Generative AI performance reports
- Google Search Central, AI features and your website
- Google, Google’s common crawlers
- Google, Verify requests from Google crawlers and fetchers
- Google Analytics Help, What’s new in Google Analytics, Default channel group, Custom channel groups, About regular expressions
- Microsoft Bing Webmaster Blog, Introducing AI Performance in Bing Webmaster Tools Public Preview
- Microsoft Bing Webmaster Tools Help, AI Performance FAQ
- Microsoft Bing Search Blog, New AI Visibility Insights in Bing Webmaster Tools
- OpenAI, Overview of OpenAI Crawlers
- OpenAI Help Center, Publishers and Developers FAQ, Temporary chat
- Anthropic, Does Anthropic crawl data from the web
- Perplexity, Perplexity Crawlers
- IndexNow.org, Documentation and FAQ
- Vercel, WAF Managed Rulesets, Firewall Observability, Runtime Logs
- Cloudflare, Managed robots.txt
- Plausible, Top referrers
- Ahrefs, Brand Radar
- Semrush, AI Visibility Toolkit